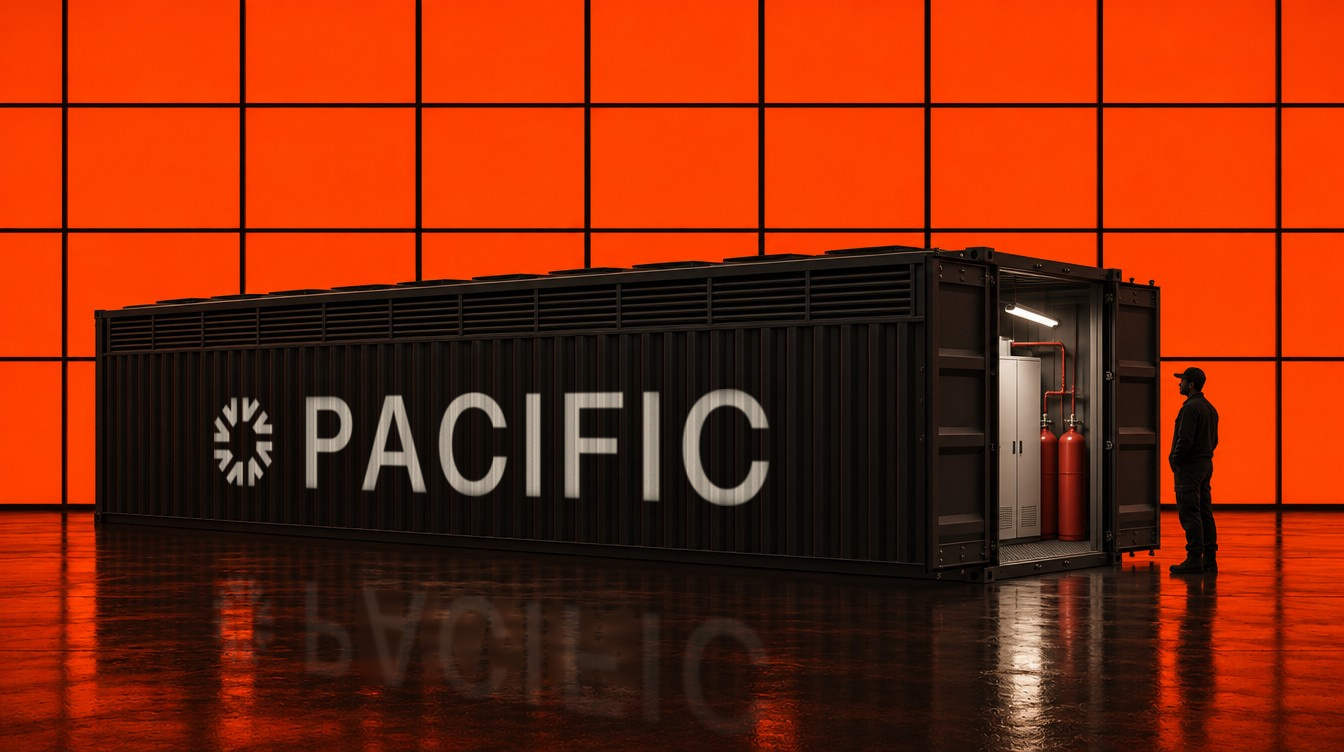
Pacific Pod 32 under a single top light in a dark hangar

Pod 32256 NVIDIA B300s in a 40 foot container

WHAT IT IS

A complete data center in a 40 foot high-cube container, with power distribution, direct-to-chip liquid cooling and 32 nodes of NVIDIA B300s, 8 to a rack across 4 racks, all in one box. Power and cooling are built in and tested at the factory before it leaves. One customer gets the whole machine as single-tenant bare metal.

HOW IT LANDS

It arrives on one truck, is dropped onto a powered pad, and switches on within days once the pad is live. Under 1 MW, so it runs on a connection that already exists. Put one on a stalled site and it earns while the big build catches up, then it leaves on the same truck it arrived on.

ONE POD OR MANY

The pod is the building block. One pod is a single megawatt site, and several clustered together form a campus, with capacity growing where and when the power becomes available.

Base configuration
GPUs
256 NVIDIA B300
Nodes
32 HGX B300 nodes, 8 per rack across 4 racks
CPUs
64 Intel Xeon 6776P
System memory
128 TB DDR5
Local NVMe
983 TB raw
Compute fabric
400G rail-optimised Ethernet, 3.2 Tbps per node
Power
645 kW operating, 790 kW design envelope, 480 V A/B feeds
Cooling
Direct-to-chip liquid, closed loop, redundant CDUs, 850 kW heat rejection

Configurable at order. Fabric to 6.4 Tbps per node, shared storage to around 200 TB.

Length: 12.2 m Width: 2.44 m 10 roof fans Louvre band, both sides 256 NVIDIA B300 GPUs inside
Work with Pacific
Work with Pacific

Pacific rents GPUs, builds managed clusters and sells pods to selected partners.
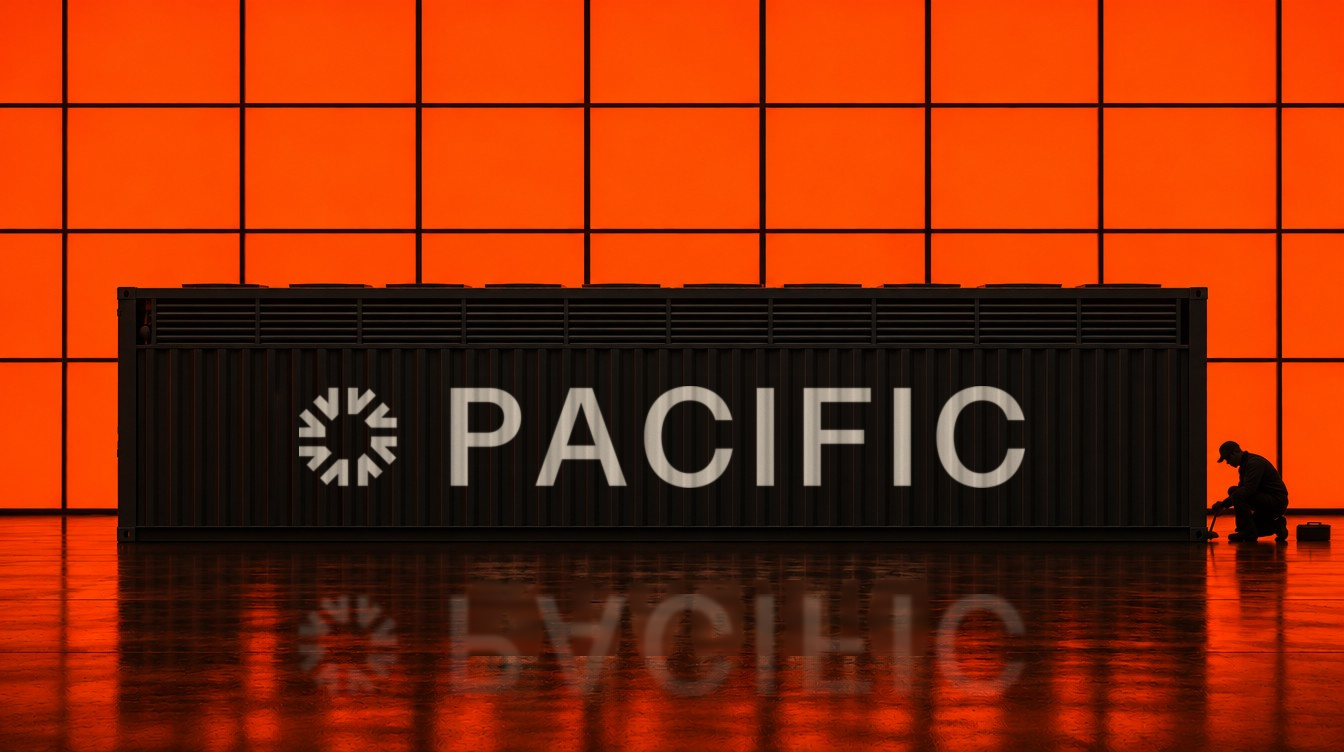
Pacific pod side-on in front of a wall of light, a technician kneeling at its corner
Pod
Buy the pod
You own the whole module. It is configured at order, and the target is operation within three months of pre-payment.
Request a pod
Pacific pod with both end doors open, rows of racks lit inside
Capacity
Rent the compute
Pacific's GPUs run as a managed cluster for your term. You are the only tenant.
Request capacity
Three Pacific pods in a row in front of a wall of light
Colocation
Bring your own GPUs
Your GPUs sit in a Pacific pod, with A and B power and liquid cooling already built in.
Request colo space
A line of Pacific pods receding between light bars

FABRIC, POWER AND COOLING

The 400G fabric is offered in two configurations, 3.2 or 6.4 Tbps per node. Power is fed on A and B paths throughout, and the cooling runs direct to chip, from cold plates through rack manifolds to the coolant distribution units, carrying the heat straight off the silicon.
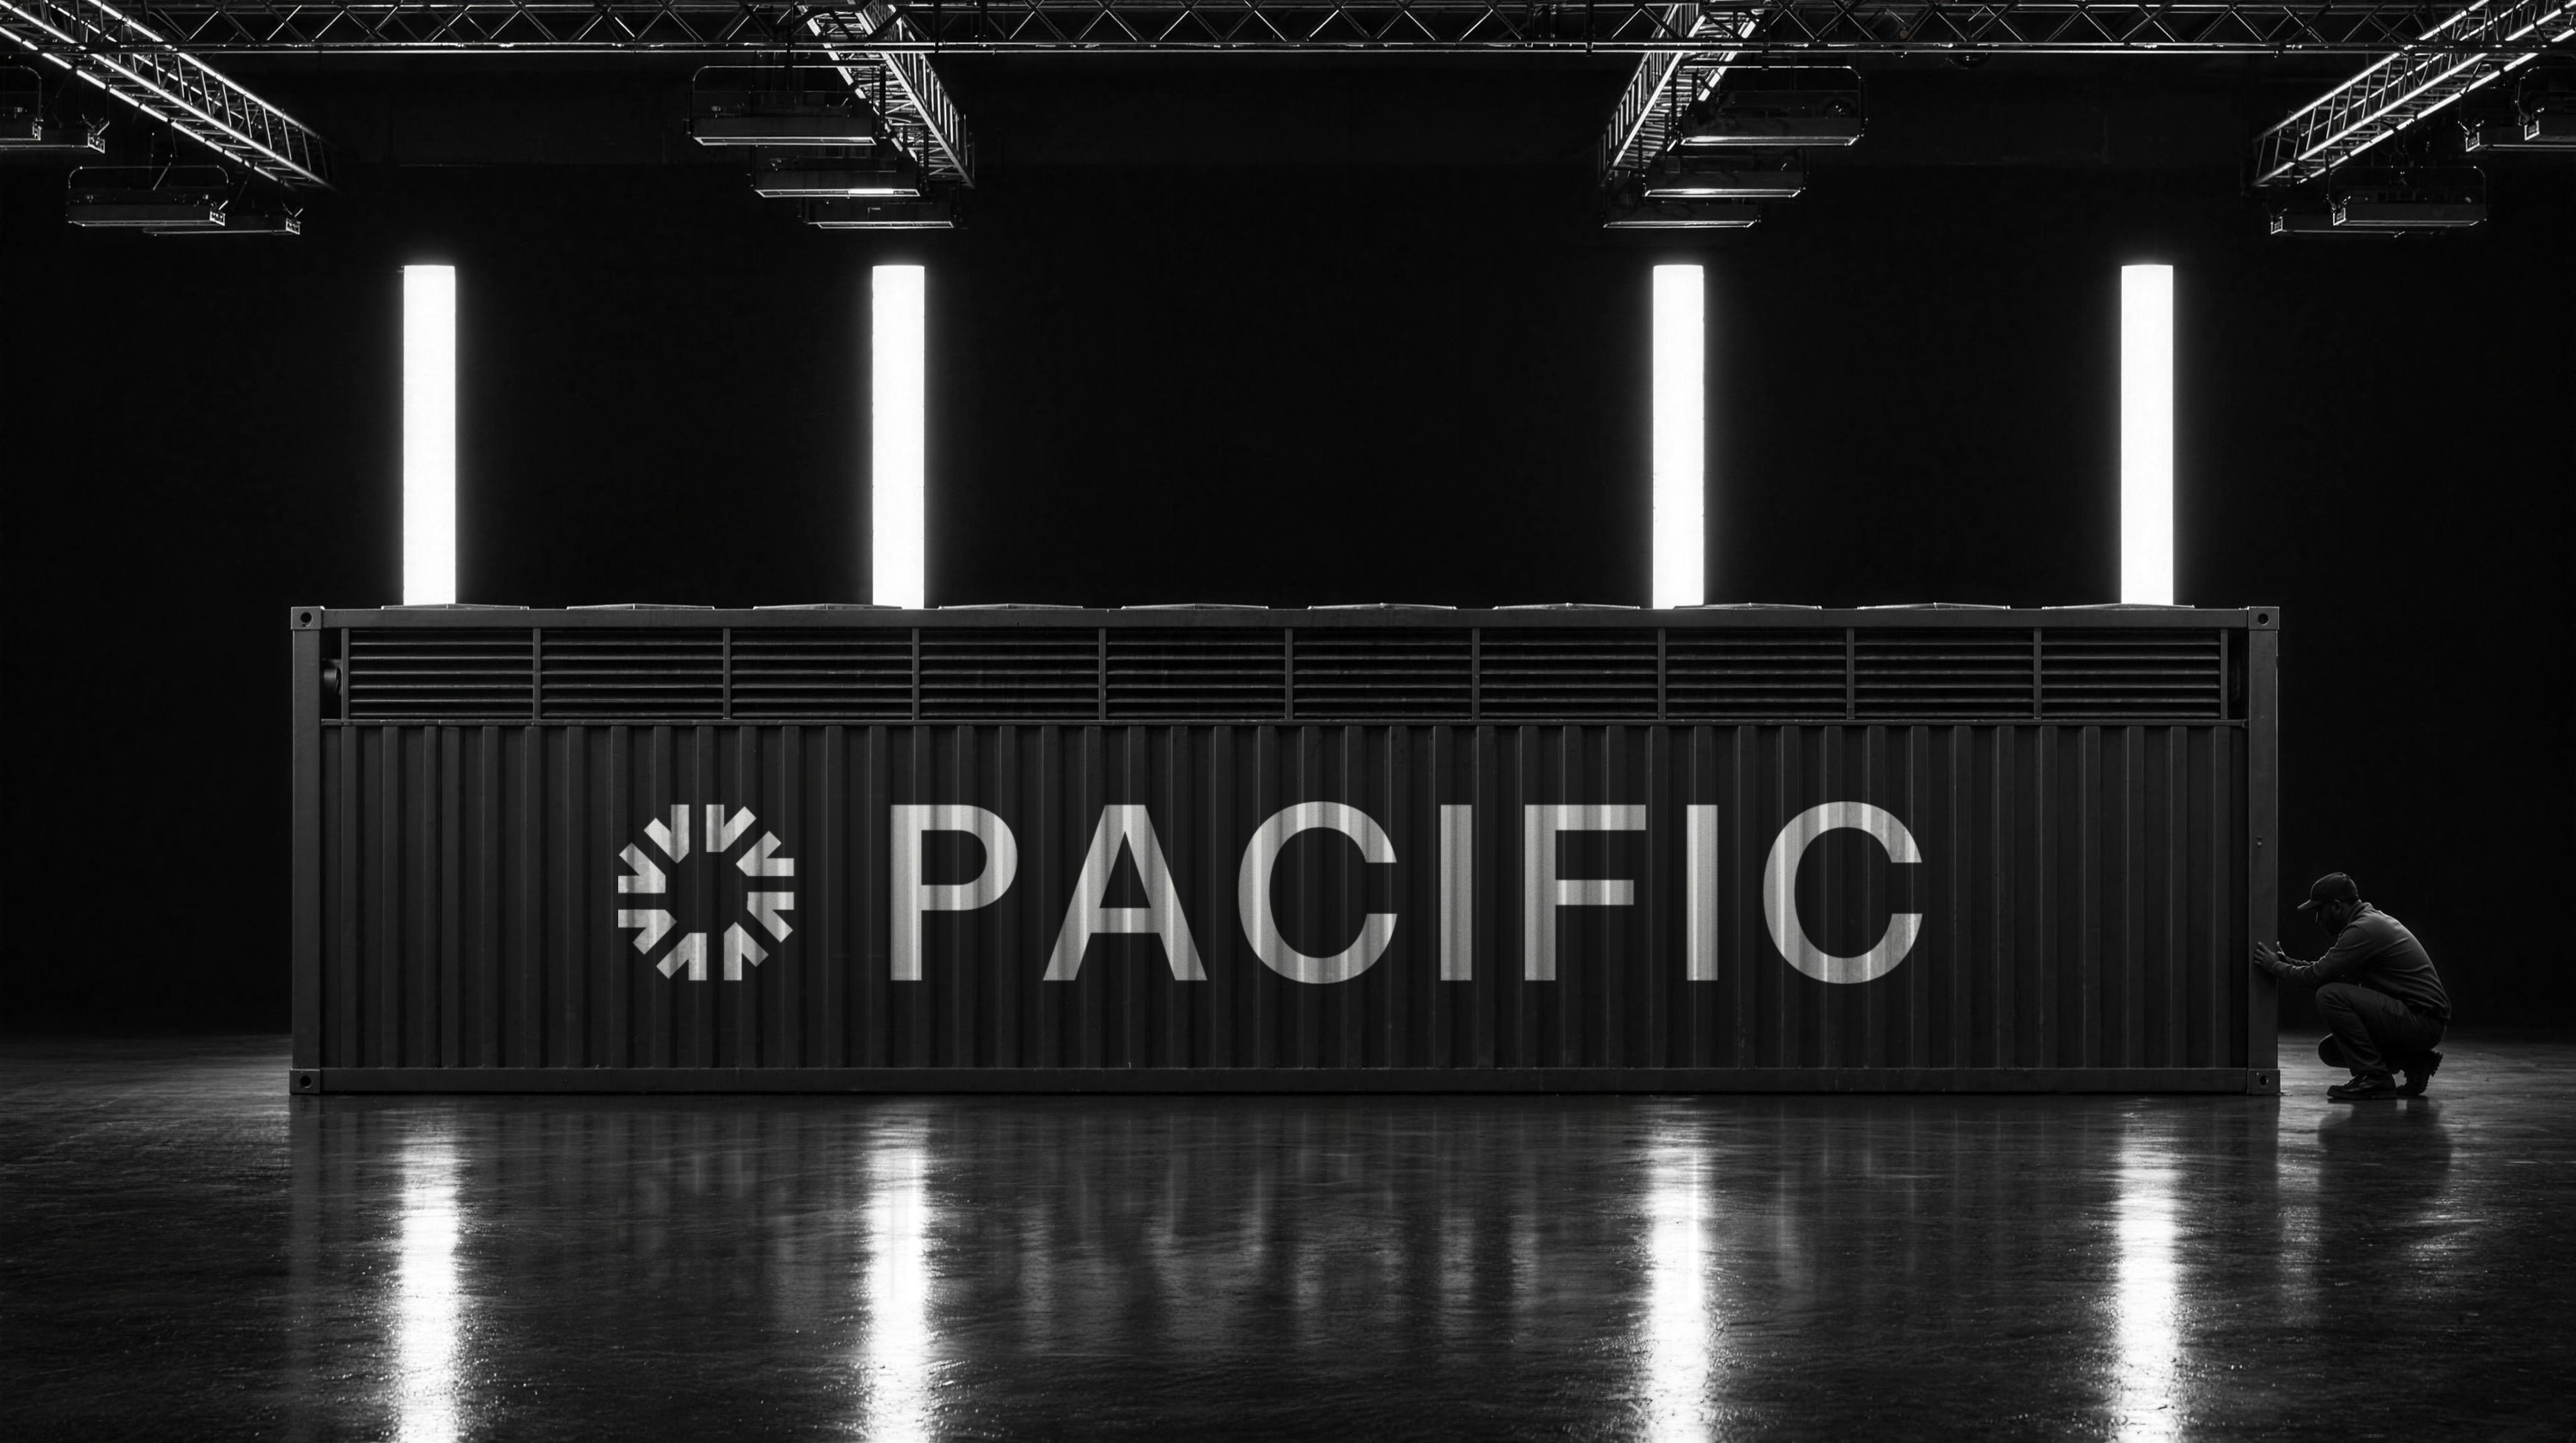
Pacific Pod 32 side-on in a hangar
Request capacity